logo
RunComfy
  • ComfyUI
  • 訓練器新
  • 模型
  • API
  • 定價
discord logo
模型
探索
所有模型
資源庫
生成記錄
模型 API
API 文檔
API 金鑰
帳戶
使用情況

Z Image Turbo:支援 6 種長寬比的文字生圖模型 | RunComfy

tongyi-mai/z-image/turbo/text-to-image

依文字生成最多 4 張圖片,並調整尺寸、步數、隨機種子與輸出格式。

要產生的圖像數量。
指定輸出影像格式。
Idle
The rate is $0.006 per image.

Z Image Turbo 文字生圖功能概覽

Z Image Turbo 會依文字提示詞生成圖片。此頁面提供 6 種固定長寬比、1–30 個推論步驟、隨機種子、每次 1–4 張圖片與 3 種輸出格式。這個版本不接收原始圖片或影片。

X 上的 Z Image Turbo

輸入項目與範圍#

  • prompt 是唯一必填項目。
  • image_size 提供 square_hd、square、portrait_4_3、portrait_16_9、landscape_4_3 與 landscape_16_9,預設為 landscape_4_3。
  • num_inference_steps 範圍為 1–30,預設值為 8。
  • seed 是整數,預設值為 0。
  • num_images 範圍為 1–4,預設值為 1。
  • output_format 支援 jpeg、png 與 webp,預設為 png。

建議流程#

在 prompt 中描述主體、環境、視角、光線與風格,再依用途選擇長寬比。建議先使用預設參數生成;比較不同設定時請維持種子不變,並一次只修改一項參數。提高 num_images 可在同一次執行中取得多張候選圖片。


相關頁面與來源#


  • Seedream 4.5 Text-to-Image
  • FLUX.2 Pro Text-to-Image
  • Nano Banana Pro Text-to-Image
  • Z Image Turbo API
  • Tongyi-MAI/Z-Image-Turbo on HuggingFace
  • Z-Image Docs
  • Z-Image Paper
  • Z Image Turbo Image-to-Image
  • Z Image Turbo Image-to-Image LoRA
  • Z Image Turbo ControlNet LoRA

價格#


The rate is $0.006 per image.


相關模型

recraft-v3/text-to-image

透過豐富的風格、尺寸與配色設定,產生點陣圖、數字插畫或向量風格圖片。

flux-1-kontext/pro/text-to-image

高精準 AI 文字轉圖像工具,支援細節調整與靈活創作。

longcat-image/text-to-image

根據文字生成圖片,提供 6 個精確尺寸預設,並可設定推理步數、引導強度、隨機種子以及 JPEG、PNG 或 WebP 輸出。

qwen-edit-2509/multi-image-edit-plus

根據 800 個字元以內的必填指令編輯 1–3 張必填來源圖片。可請求 1–6 張結果,新增 500 個字元以內的負面提示詞,並設定 0–2147483647 的隨機種子。

gpt-image-2.5/flare/edit

針對創作者內容、社交貼文和產品變體進行基於參考的快速圖像編輯。

stepx-edit2

根據文字指令編輯一張來源圖片,並可設定反向提示詞、隨機種子、思考與反思模式,以及 JPEG 或 PNG 輸出。

常見問題

此頁面的 Z Image Turbo 可以做什麼?

它會依文字提示詞生成一張或多張圖片。這個版本屬於文字生圖模型。

哪個輸入項目是必填的?

只有 prompt 必填。

支援哪些長寬比?

可選 square_hd、square、portrait_4_3、portrait_16_9、landscape_4_3 與 landscape_16_9,預設為 landscape_4_3。

推論步數可以設定為多少?

num_inference_steps 範圍為 1–30,預設值為 8。

一次可以生成多少張圖片?

num_images 可設為 1–4,預設值為 1。

支援哪些檔案格式?

可選 jpeg、png 或 webp,預設為 png。

隨機種子的預設值是什麼?

seed 是整數,預設值為 0。

可以提供原始圖片或影片嗎?

不可以。此 schema 只有文字提示詞,沒有原始圖片或影片輸入項目。

提示詞應該怎麼寫?

先寫主要主體,再用清楚的語句補充環境、構圖、光線、視角與風格。

如何合理比較兩組設定?

維持提示詞、圖片尺寸與隨機種子一致,每次只改變一個值,例如推論步數,如此較容易判斷參數帶來的影響。

關注我們
  • 領英
  • Facebook
  • Instagram
  • Twitter
支持
  • Discord
  • 電子郵件
  • 系統狀態
  • 附屬
視頻模型
  • Wan 2.5
  • Wan 3.0
  • Wan 2.6 Flash
  • MiniMax H3 Max
  • Wan 3.0 Prime
  • Wan 2.7 Image to Video
  • 查看所有模型 →
影像模型
  • Nano Banana 2.1 Edit
  • Nano Banana 2.1
  • Wan 2.6 Image to Image
  • Seedream 5.0 Pro
  • Nano Banana Pro
  • Flux 2 Max Edit
  • 查看所有模型 →
法律
  • 服務條款
  • 隱私政策
  • Cookie 政策
RunComfy
版權 2026 RunComfy. 保留所有權利。

RunComfy 是首選的 ComfyUI 平台,提供 ComfyUI 在線 環境和服務,以及 ComfyUI 工作流程 具有驚豔的視覺效果。 RunComfy還提供 AI Models, 幫助藝術家利用最新的AI工具創作出令人驚艷的藝術作品。
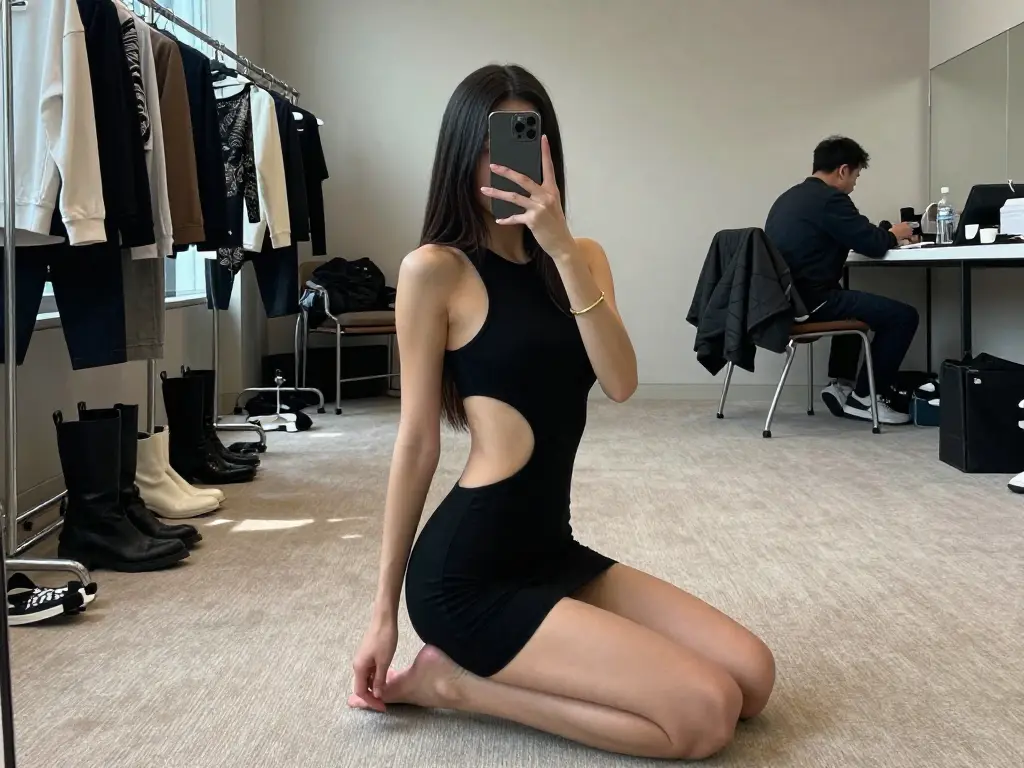
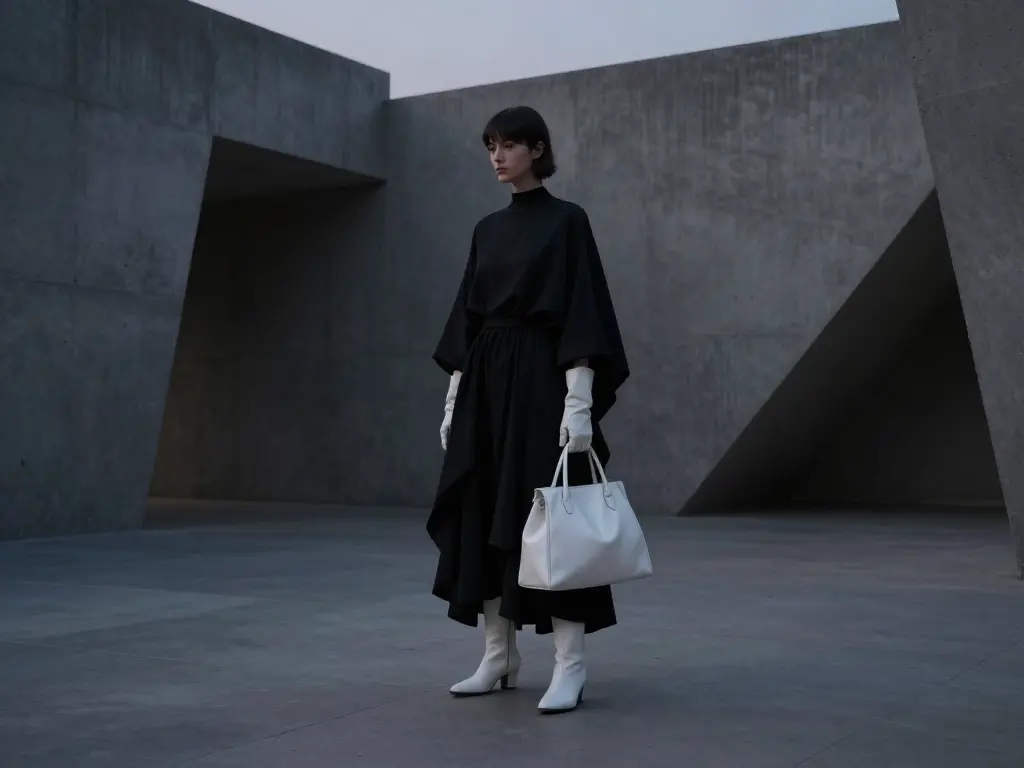
Z Image Turbo 生成範例

Woman in cut-out black dress kneeling in a fashion studio captured using Z Image Turbo
Minimalist fashion editorial of a woman in black and white attire posing in a concrete architectural space using Z Image Turbo
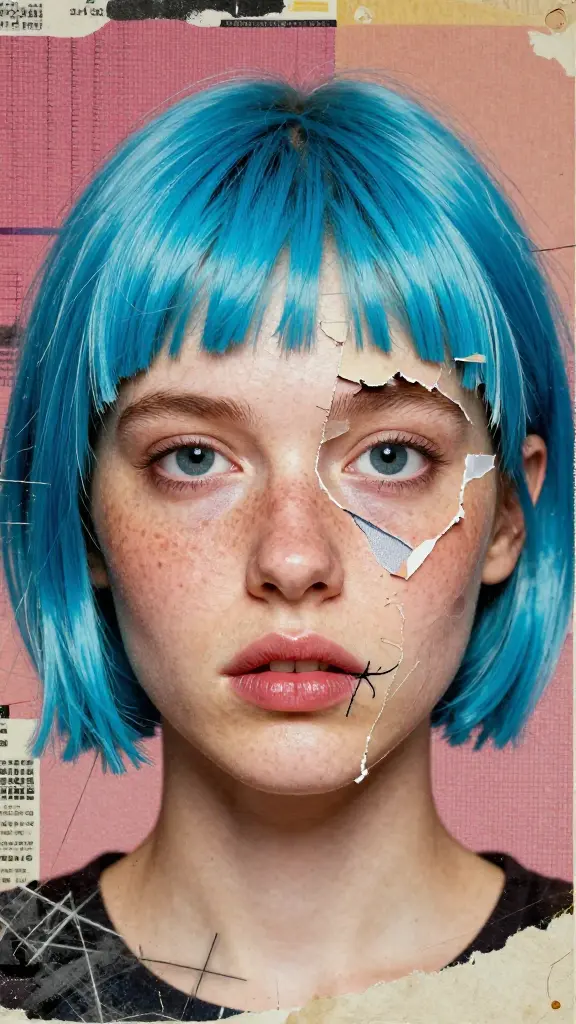
Surreal female portrait with cyan-blue hair and torn paper effect on her face, created with Z Image Turbo
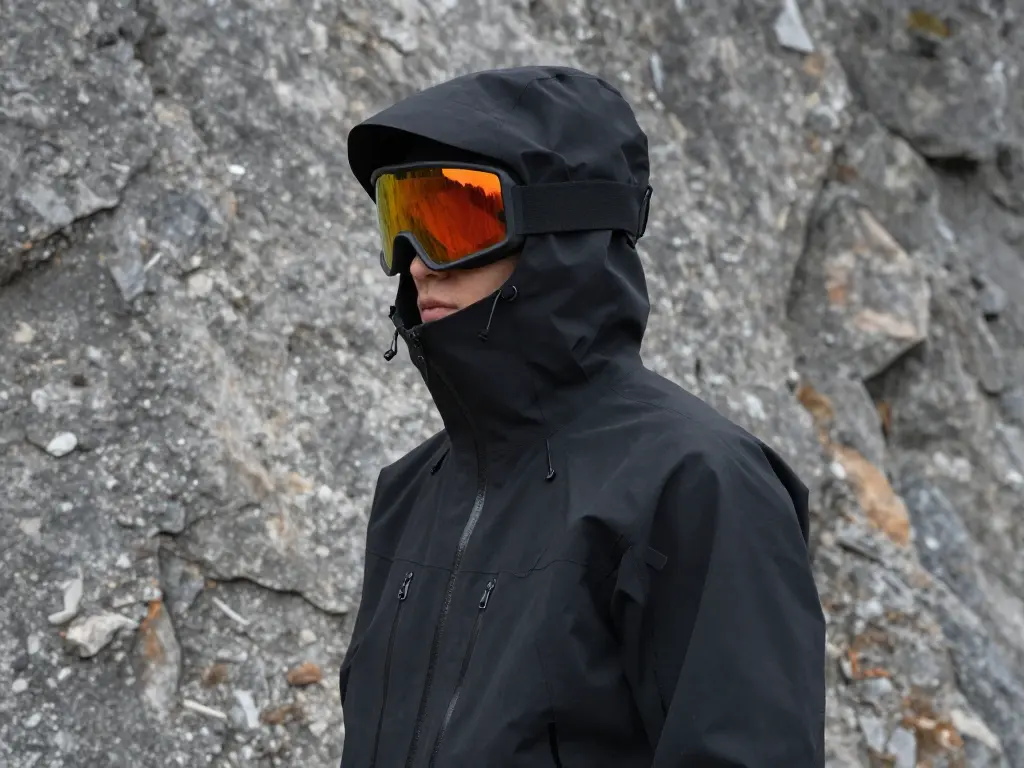
Person in black techwear jacket and mirrored goggles near rocky terrain, rendered with Z Image Turbo.
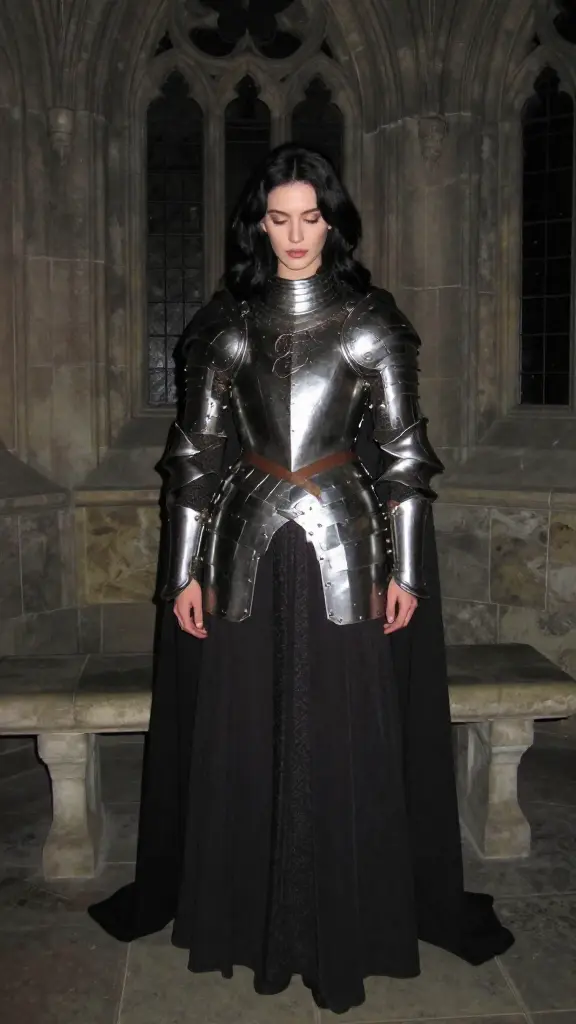
Female knight in polished medieval armor standing in a Gothic stone hall, created using Z Image Turbo
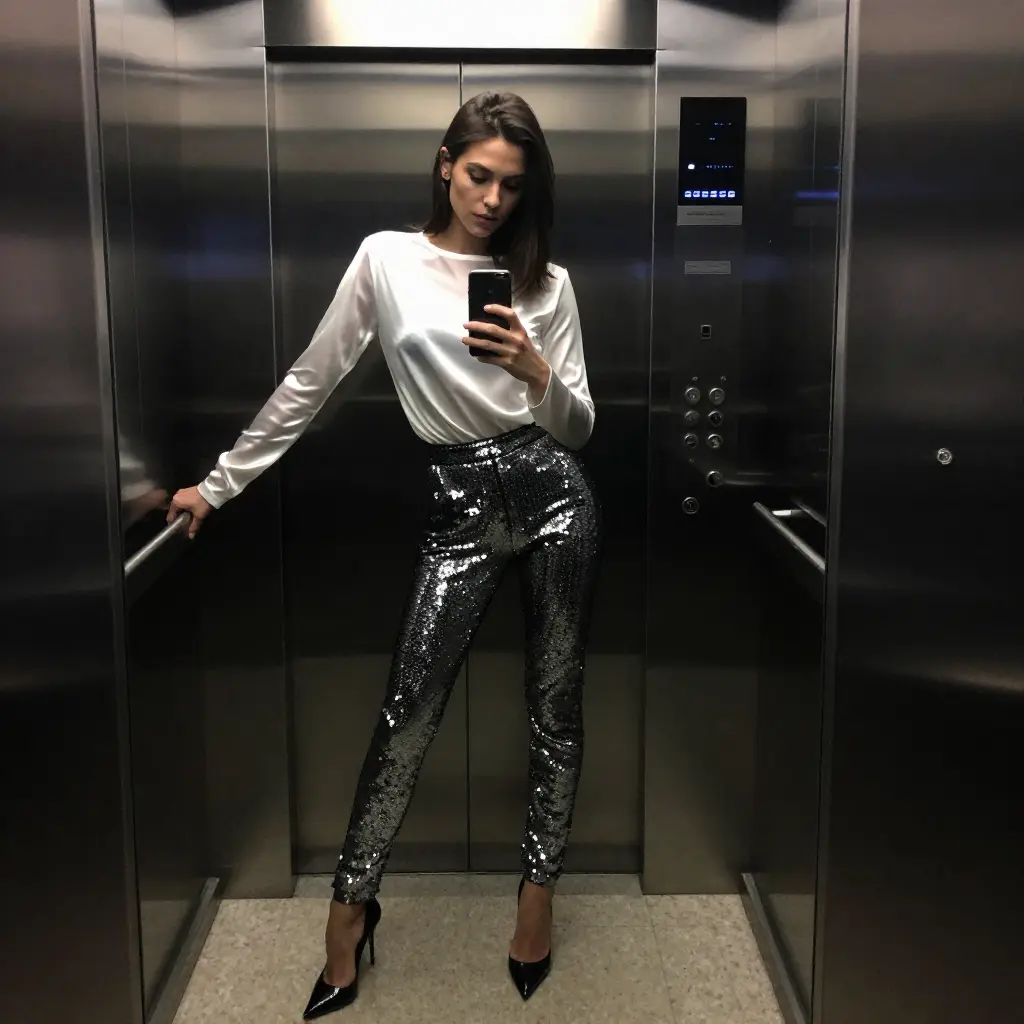
Fashionable woman taking a mirror selfie in an elevator wearing sequin pants and a white blouse, rendered using Z Image Turbo
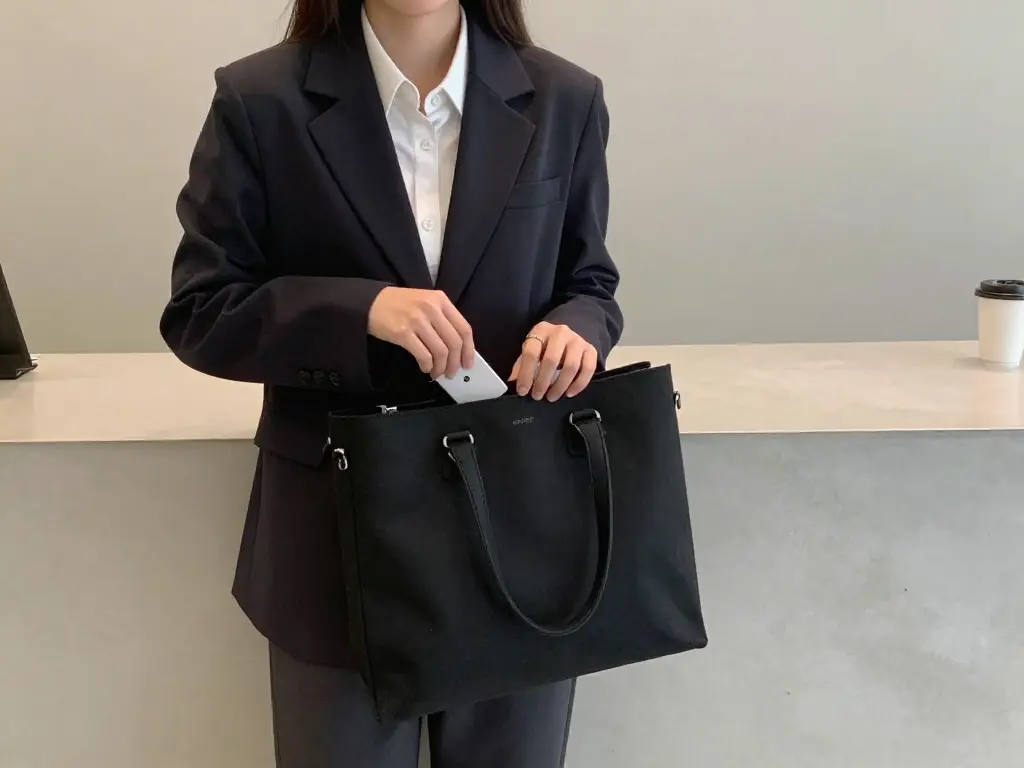
Woman wearing a black blazer places a phone into a black tote bag in a minimalist setting, created using Z Image Turbo
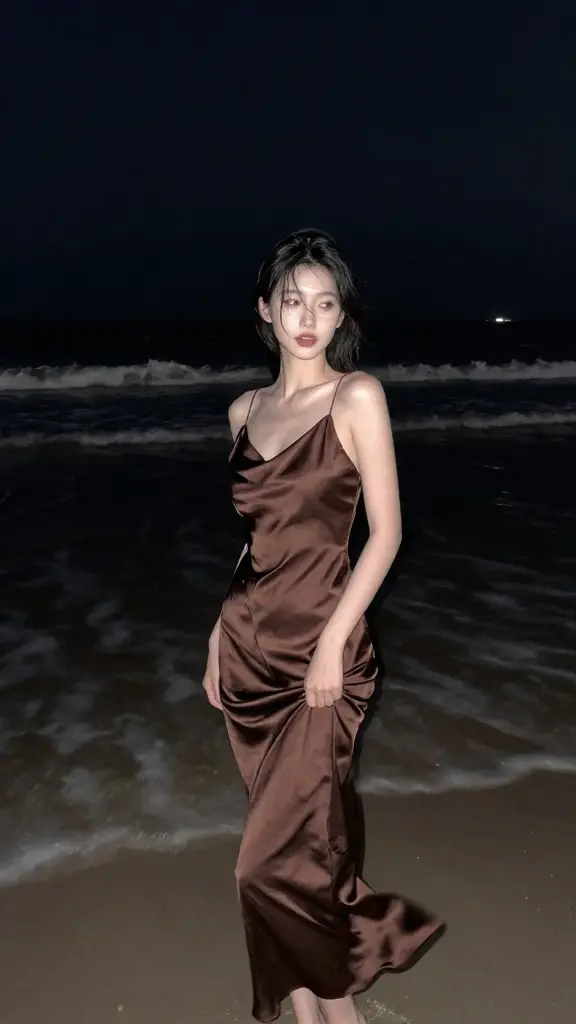
Woman in a silk brown dress walking on a beach at night, styled with Z Image Turbo
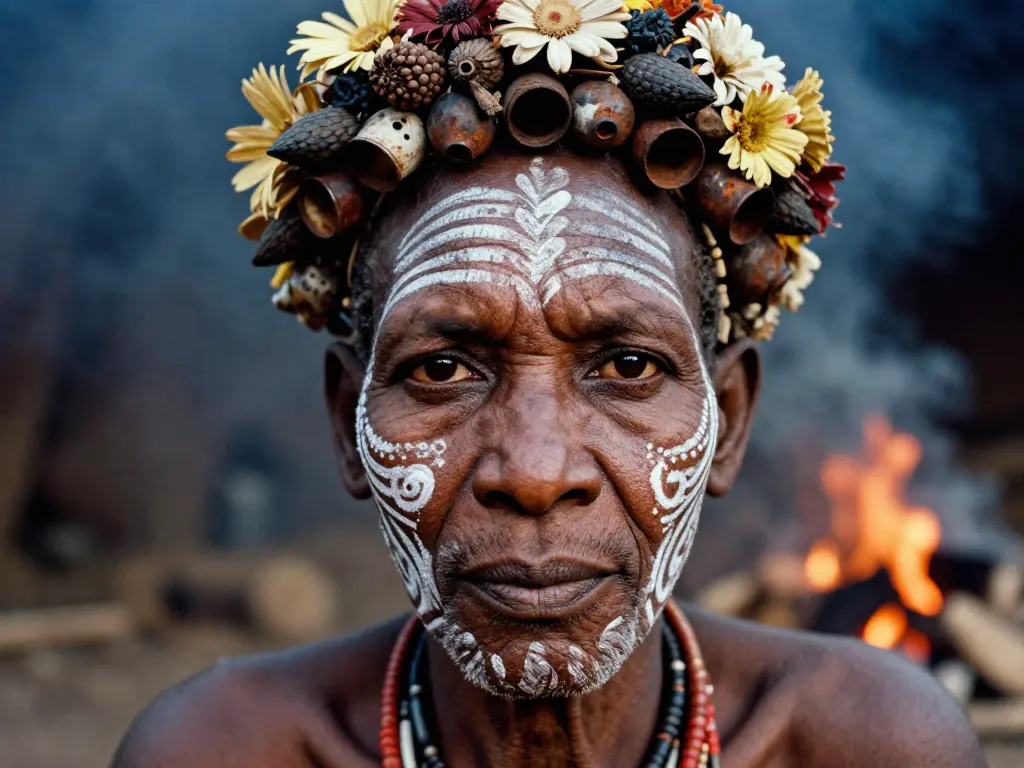
Portrait of an elder with tribal face paint and floral crown, created using Z Image Turbo