seedream-4-0/sequential
Create cohesive story visuals with sequenced, style-stable image generation.
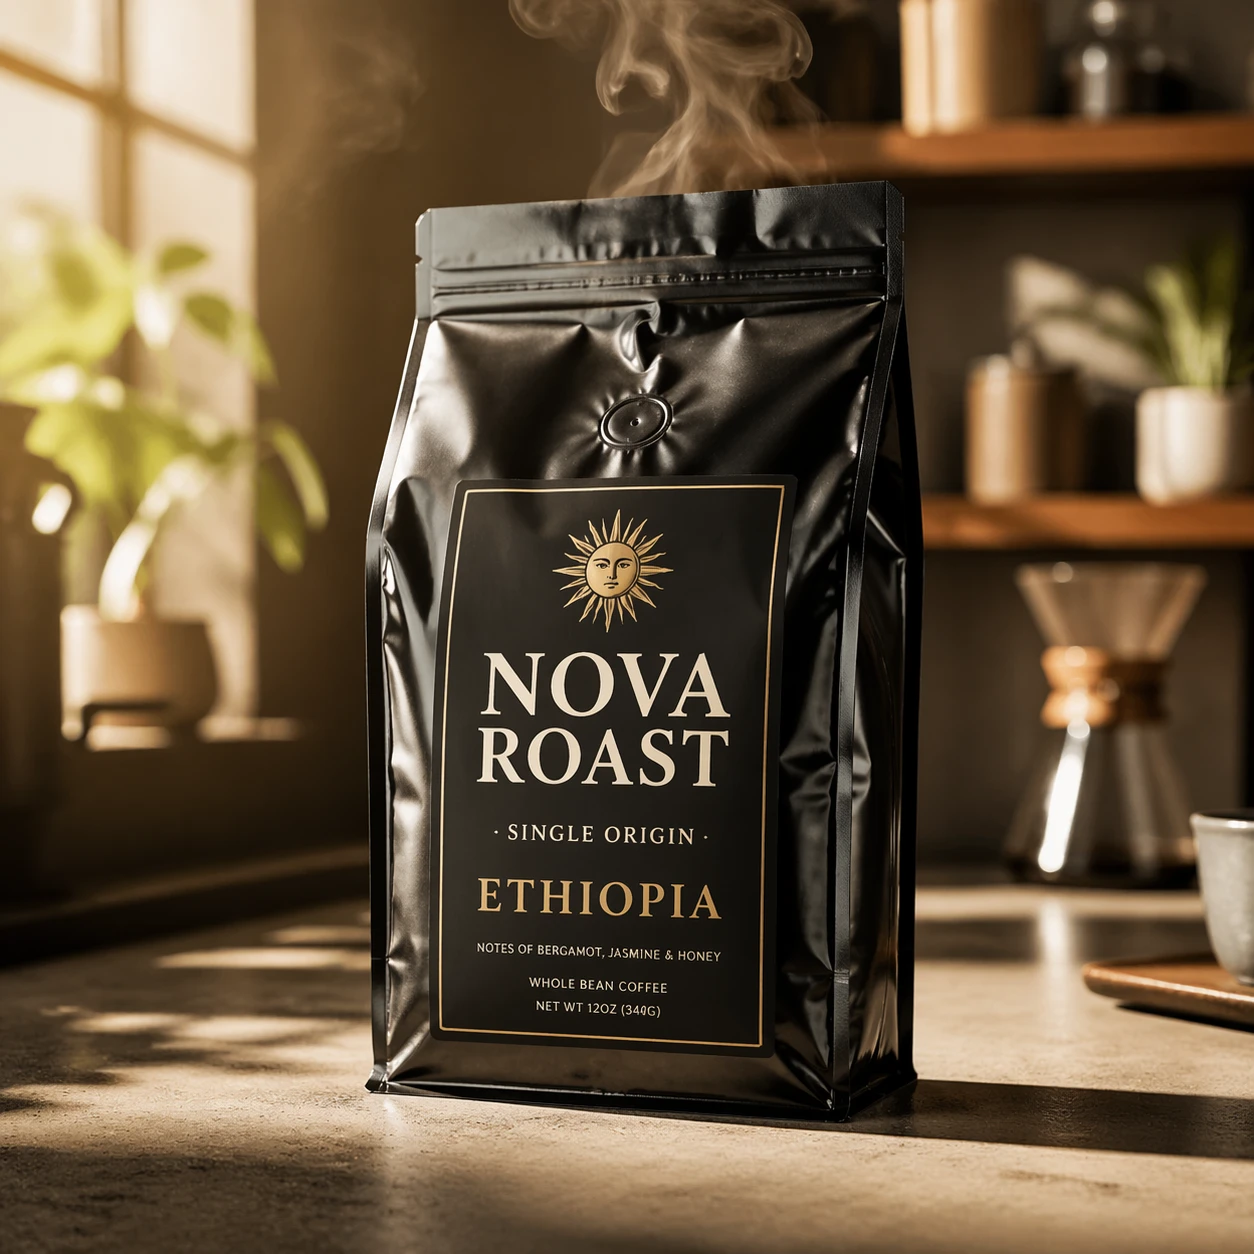
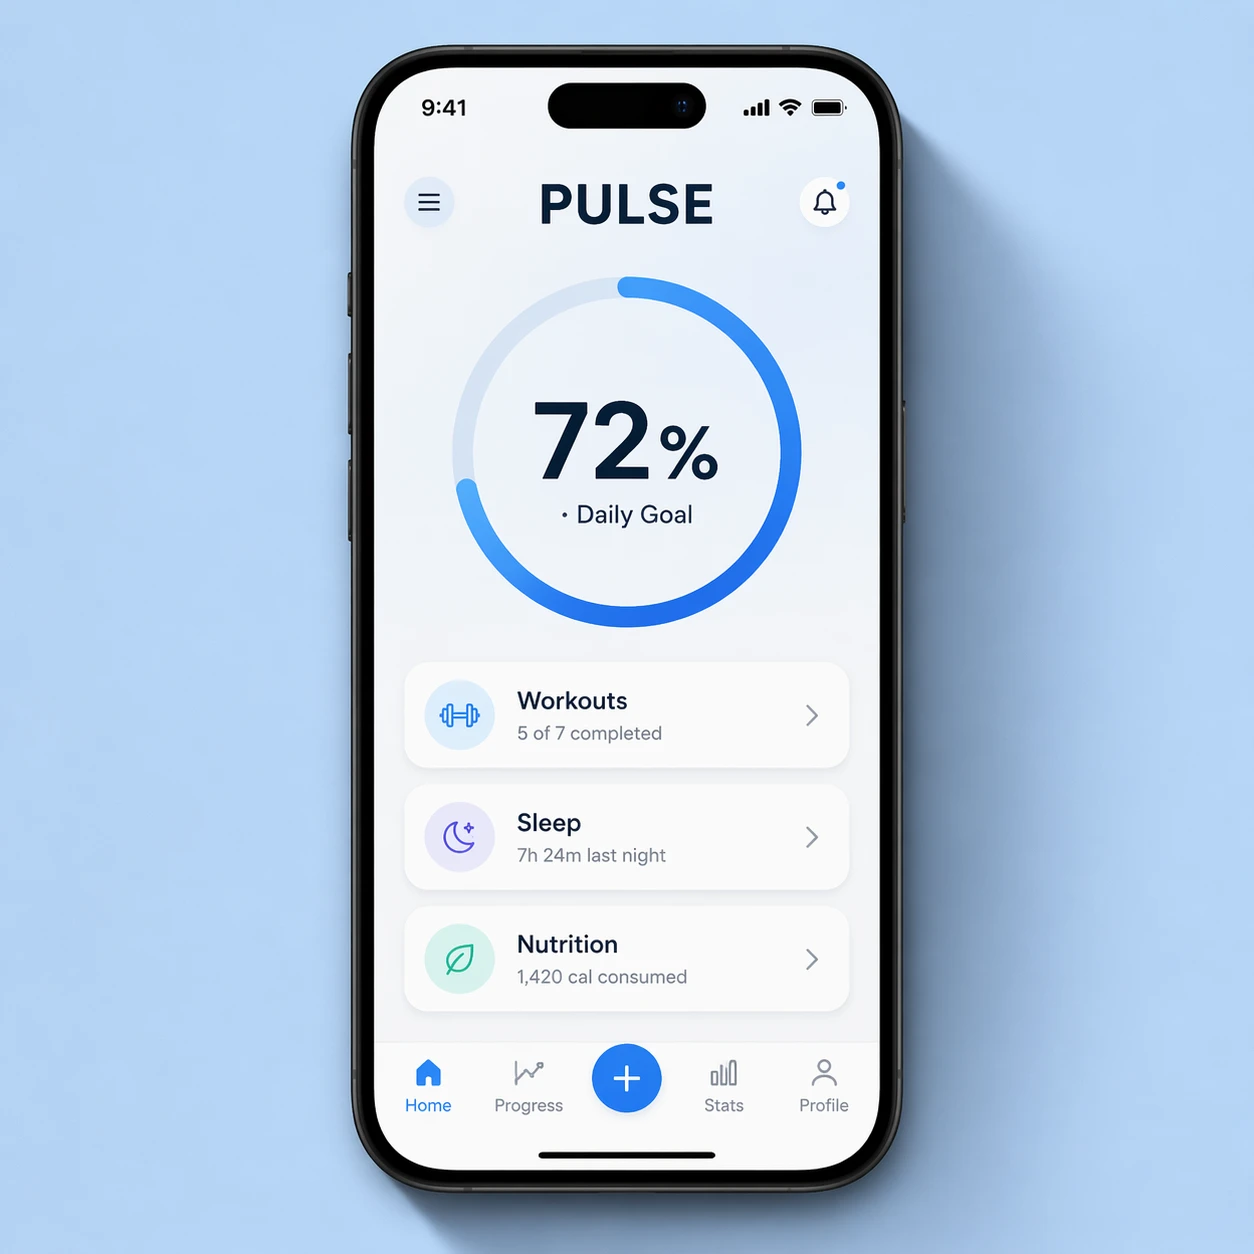
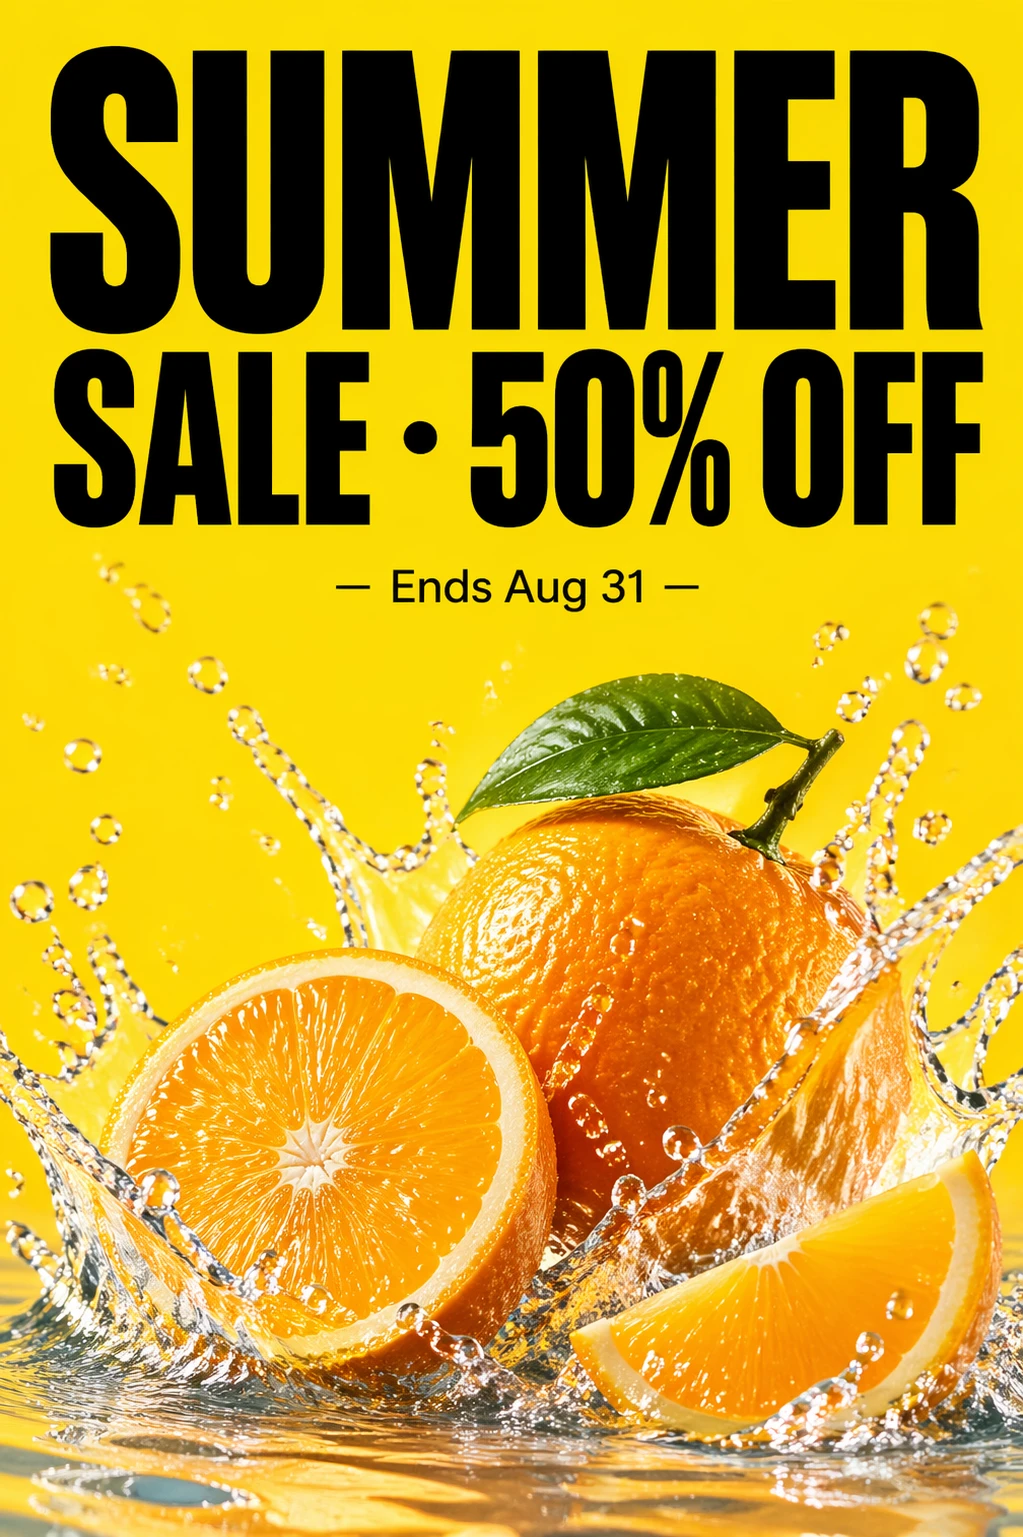
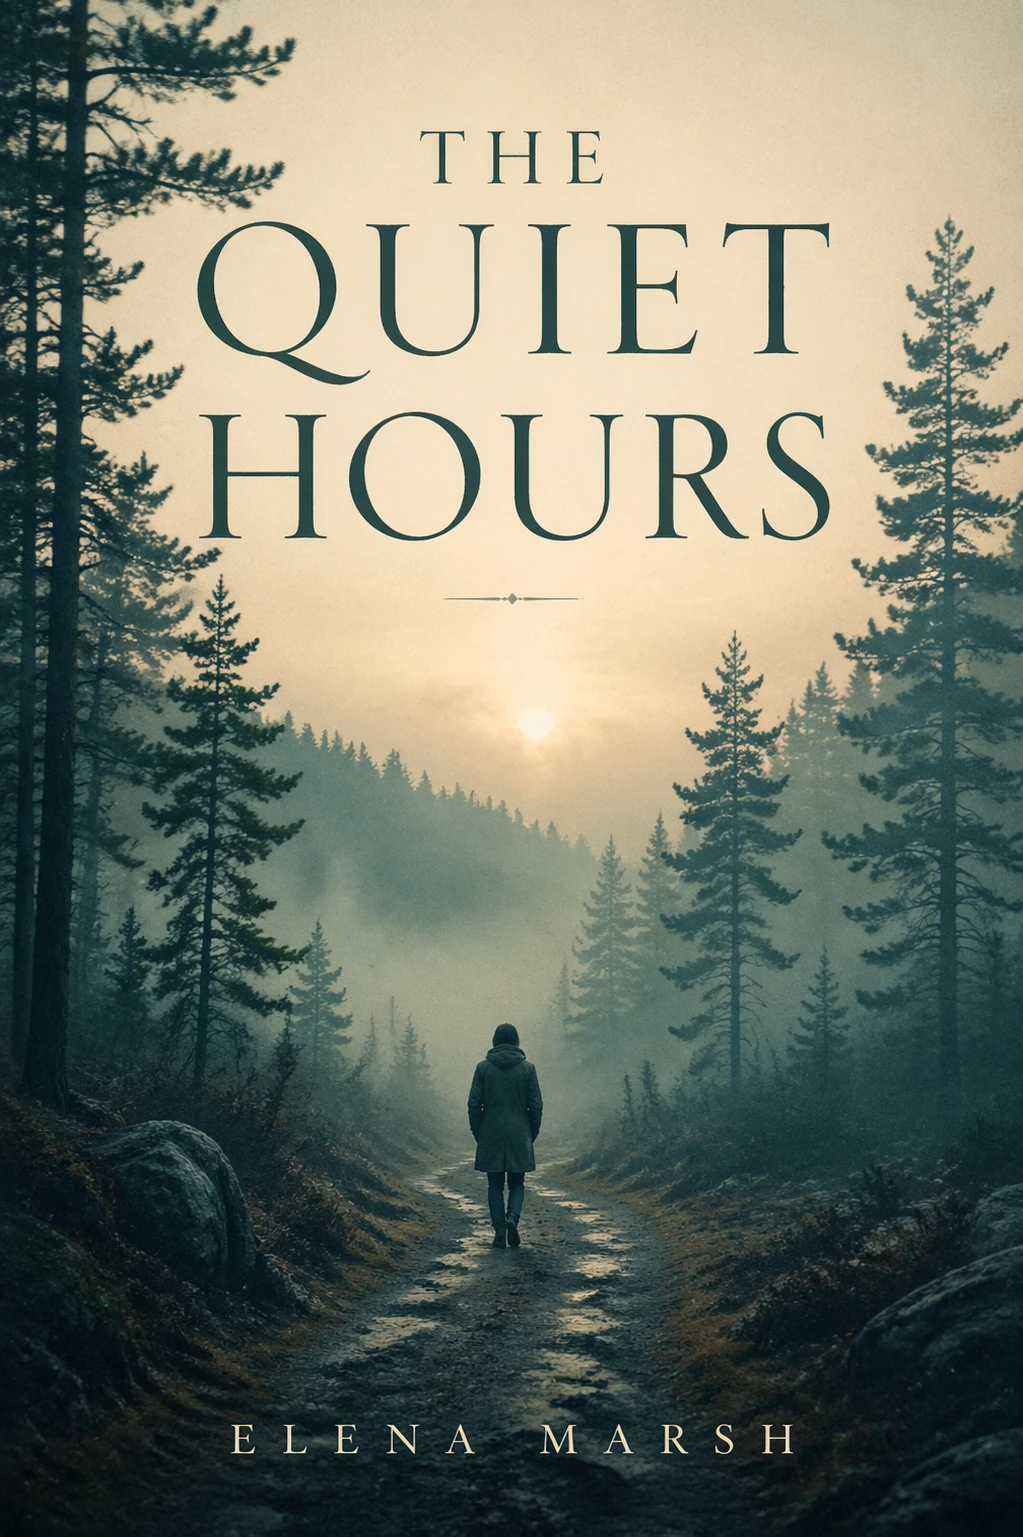
OpenAI's GPT Image 2 turns text into production-ready images from $0.02 per image, with precise in-image text and logo rendering. Trading manual photoshoots, stock hunting, and complex masking for instruction-faithful generation, multilingual text rendering, and consistent brand visuals, GPT Image 2 streamlines asset creation and eliminates tedious layout guesswork, built for e-commerce teams, designers, and marketing workflows. For developers, GPT Image 2 on RunComfy can be used both in the browser and via an HTTP API, so you don’t need to host or scale the model yourself.
Ideal for: E-commerce Product Imagery | High-Conversion Ad Visuals | Brand Asset Localization
GPT Image 2 is a text-to-image generation model from OpenAI that takes a written prompt and returns a high-quality image. On RunComfy, it accepts a text prompt and supports selectable output resolution and aspect ratio, making it suitable for product mockups, marketing visuals, concept art, and design exploration.
Output format: Resolution: 1K, 2K, 4K / fps: n/a / duration: n/a / aspect ratio: 1:1, 3:2, 2:3, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 21:9 / audio: n/a
| Parameter | Required | Type | Default | Range / Options | Description |
|---|---|---|---|---|---|
| prompt* | Yes (*) | string | — | — | The positive prompt for the generation. |
| resolution | No | string | 1K | 1K, 2K, 4K | The output resolution tier of the generated image. |
| aspect_ratio | No | string | 1:1 | 1:1, 3:2, 2:3, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 21:9 | The aspect ratio of the generated image. |
In short, GPT Image 2 on RunComfy offers a balanced mix of quality, control, and dependable text rendering for production workflows.
Create cohesive story visuals with sequenced, style-stable image generation.

Precision-focused reference image editing for campaign artwork and polished product visuals.

Fast, photorealistic image repair and refinements for product visuals.

Create photoreal visuals with multi-reference, color, and typography precision.

Redefine creative edits with dual-input precision and adaptive control for design professionals

Keep one face and restage pose, clothes, and light from a reference photo.
GPT Image 2 introduces enhanced instruction following, support for up to 4K resolution, and significantly better text rendering within images. This text-to-image model also supports multilingual prompts, offering creators more flexibility across languages and visual detail than earlier GPT Image versions.
GPT Image 2 supports up to ~8.3 million total pixels (approximately 4K resolution) and a minimum limit of around 655,360 pixels per image. Aspect ratios are flexible, but extremely wide or tall frames are auto-resized. Prompt token limits follow standard OpenAI API constraints—typically a few thousand tokens for text-to-image tasks.
At present, GPT Image 2 allows a single reference image input for inpainting or editing, but does not officially support multiple concurrent image inputs like a full ControlNet stack would. However, advanced wrappers or layer-based approaches may simulate dual input reference for text-to-image consistency.
You can start with the RunComfy Playground at https://www.runcomfy.com/playground to experiment with GPT Image 2 using free trial credits. For production, switch to the RunComfy API layer, which uses similar endpoints to the playground. Authentication and model selection parameters remain consistent—simply set the model parameter to 'gpt-image-2-2026-04-21' for consistent text-to-image results.
Yes. GPT Image 2 is competitive in photorealism, particularly in product, studio, and branding use cases. While some rivals like Nano Banana Pro remain slightly ahead in hyperrealistic portraits, GPT Image 2 excels in layout accuracy, multilingual text inclusion, and faithful reproduction of logos—all key for high-end text-to-image workflows.
GPT Image 2’s architecture is optimized for accurate layout and sharpness when generating embedded text or logos. This means that signage, captions, or brand marks appear more naturally integrated—a major step forward for text-to-image generation consistency.
Yes. GPT Image 2 supports multilingual understanding and rendering, including Japanese, Korean, Chinese, Hindi, and Bengali, enabling native-language captions or labels to appear inside generated imagery without manual post-processing.
The intelligent routing layer in GPT Image 2 automatically chooses optimal generation settings—resolution, composition ratio, and resource allocation—based on your text-to-image prompt. This reduces trial-and-error and ensures consistent quality for both prototyping and high-throughput production.
GPT Image 2 performs best when instructions, structure, and clarity are vital—such as product photography, advertising, UI mockups, or scientific illustrations. While artistic models like Flux 2 may excel in stylized imagery, GPT Image 2 leads in precise, directive text-to-image generation and consistent visual logic.
RunComfy is the premier ComfyUI platform, offering ComfyUI online environment and services, along with ComfyUI workflows featuring stunning visuals. RunComfy also provides AI Models, enabling artists to harness the latest AI tools to create incredible art.