logo
RunComfy
  • ComfyUI
  • TrainerNew
  • Models
  • API
  • Pricing
discord logo
MODELS
Explore
All Models
LIBRARY
Generations
MODEL APIS
API Docs
API Keys
ACCOUNT
Usage

GPT 4o Image Generation | Text to Image

openai/gpt-4o-image/text-to-image

Create photorealistic, text-accurate visuals with strong prompt adherence, style control, and reliable layout for design, advertising, and polished creative content.

Idle
The rate is $0.11 per image.

Introduction of GPT 4o Image Generation

GPT 4o Image Generation, developed by OpenAI and released in April 2025, is a natively multimodal image generator built into GPT-4o. Designed to create precise, photorealistic, and useful visuals, GPT 4o Image Generation excels at accurate text rendering, prompt following, and style control.

Features of GPT 4o Image Generation

Accurate Text and Symbol Rendering

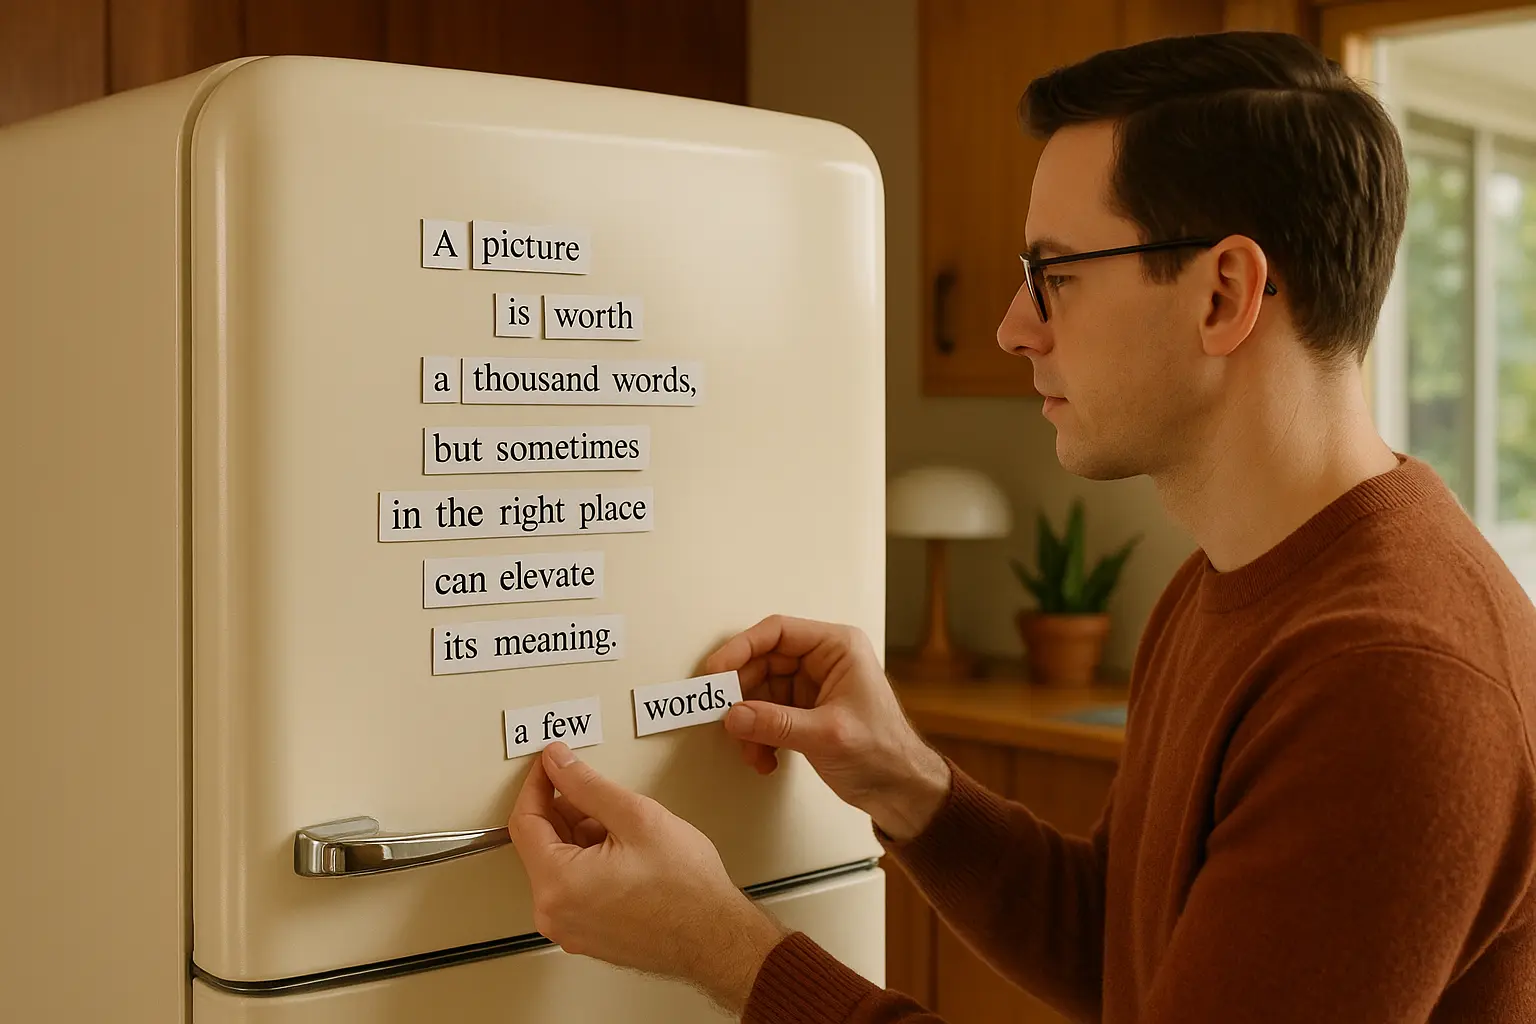
GPT-4o Image can reliably generate images that include clear, correctly spelled text and precise symbols. It handles everything from street signs and menus to diagrams and infographics, making it a practical tool for visual communication, not just artistic scenes.

Strong Prompt Following and Visual Control

GPT-4o Image excels at following detailed prompts, allowing users to specify complex scenes with up to 10-20 objects without losing clarity. It tightly binds traits to objects, giving users more predictable, accurate control over the final image.

In-Context Learning with Uploaded Images

GPT-4o Image can analyze user-uploaded images and naturally incorporate their details into new generations. This helps users create visuals that stay consistent with reference materials, designs, or themes without needing separate tools.

Broad Visual Style Range and Photorealism

Trained on a wide variety of image styles, GPT-4o Image can create photorealistic outputs, artistic illustrations, and even vintage or surreal looks. It adapts easily to the style or mood users ask for, supporting a broad range of creative and professional needs.

Related Models

z-image/turbo/text-to-image/lora

Generate detailed visuals from text swiftly with high fidelity and dual-language control.

gpt-image-2.5/flare/edit

Fast reference-based image editing for creator content, social posts, and product variations.
flux-1-kontext/pro/text-to-image

Fast, precise, iterative AI image editing model.

qwen-edit-2509/lora/relight

Advanced relighting and multi-image fusion tool with fast ControlNet support for detailed, consistent design results.

seedream-4-5/sequential

Create cohesive 4K visuals with stable subjects and refined scene alignment.

seedream-5.0-pro/text-to-image

Text-to-image and image editing with layout and layer control

Follow us
  • LinkedIn
  • Facebook
  • Instagram
  • Twitter
Support
  • Discord
  • Email
  • System Status
  • Affiliate
Video Models
  • Wan 3.0
  • Wan 2.5
  • Wan 2.6 Flash
  • PixVerse V6
  • MiniMax H3 Max
  • MiniMax H3 Open Image to Video
  • View All Models →
Image Models
  • Wan 2.6 Image to Image
  • Seedream 5.0 Pro
  • seedream 4.0
  • Nano Banana Pro
  • Gemini 3 Pro
  • Z Image Turbo LoRA
  • View All Models →
Legal
  • Terms of Service
  • Privacy Policy
  • Cookie Policy
RunComfy
Copyright 2026 RunComfy. All Rights Reserved.

RunComfy is the premier ComfyUI platform, offering ComfyUI online environment and services, along with ComfyUI workflows featuring stunning visuals. RunComfy also provides AI Models, enabling artists to harness the latest AI tools to create incredible art.